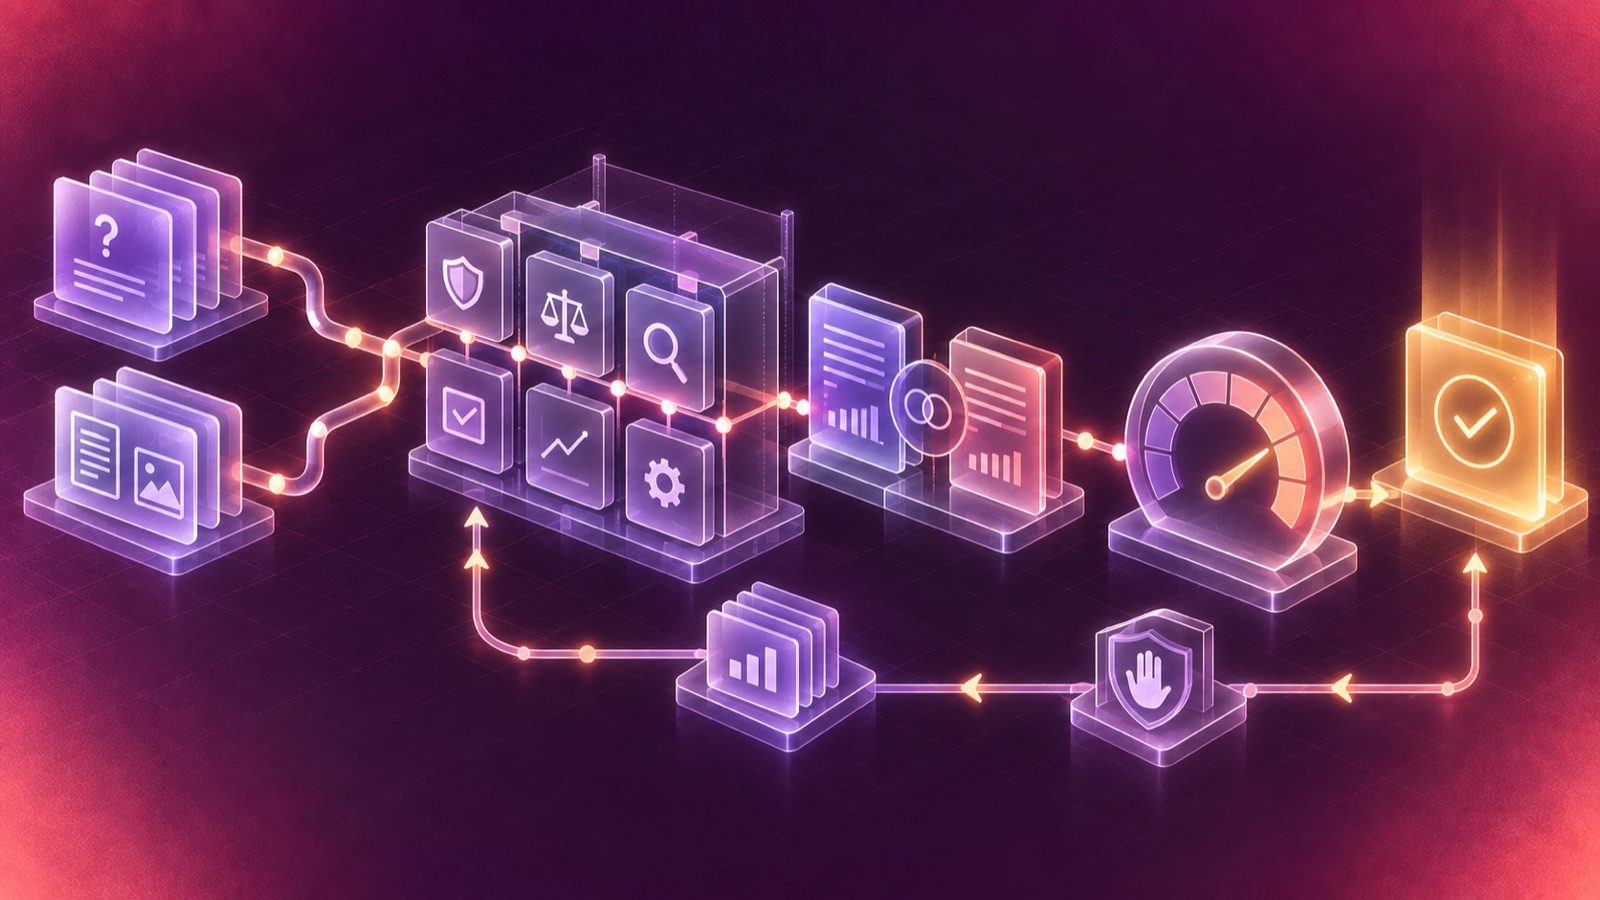
Everyone is shipping assistants. Few can say how good theirs is. The evaluation habit that separates a demo from a system you can improve on purpose.
A demo of a language model assistant takes an afternoon. A version that a company can put in front of customers, or trust with its safety documentation, takes months, and almost all of the difference is measurement. Ask a team how good their assistant is and you will usually get an adjective. Ask how they know and the room goes quiet. This is the habit we insist on before anything generative goes live, and why we think of the evaluation suite as the real deliverable.
Start with fifty real questions
Before choosing a model, a framework or a vector store, collect the questions the system will actually face. Not invented ones. Real tickets, real emails, real things guests typed into the chat window at midnight. Fifty is enough to start; a few hundred is comfortable. For each one, write down what a good answer contains and, just as important, what it must not contain.
This set is worth more than any component of the system, because it is the only thing that lets you compare two versions honestly. When someone proposes a new prompt, a different model or a retrieval tweak, the question is no longer “does this feel better?” but “what did the score do?”
Score automatically, review by hand where it matters
Some checks are mechanical. Did the answer cite a source? Does the cited passage actually contain the claim? Did the response stay inside the allowed topics? Did it refuse when it should have? Those run on every change in seconds.
Quality of the answer itself is harder. We use a second model as a grader against the reference notes, and we calibrate it by having a person grade a sample of the same answers. Where the two disagree often, the rubric is unclear and gets rewritten. Where they agree, the grader runs unattended. The output is a number per version, tracked over time, with the worst-scoring questions listed so someone can read them.
Retrieval is where most failures live
When an assistant answers wrongly, the model is usually blamed. In our experience the retrieval step is at fault more often: the right document was never fetched, or the wrong chunk of it was, or an outdated version won. So we evaluate retrieval on its own, with a simple question: for each test query, was the passage a human would have used among the results? That metric moves independently of the model, and improving it is cheap compared to switching providers.
This is also why the model choice matters less than people expect. A smaller model with precise retrieval regularly beats a larger one working from the wrong context, at a fraction of the cost. For clients whose data cannot leave the EU, it means open-weight models hosted in EU regions are a realistic option rather than a compromise.
Extraction needs validation, not vibes
Not every generative system chats. One of ours reads safety data sheets, thousands of supplier PDFs in inconsistent formats, and turns hazard information into structured fields. The evaluation there is stricter: every extracted field is checked against rules, ranges and cross-field consistency, and every value is traceable to the exact passage it came from. A field that fails validation goes to a person; nothing else does. The score that matters is the share of documents that pass without a human touch, and the share of the rest where the human agrees with the flag.
Guardrails are test cases too
Permissions, personal data and prompt injection are not features you add at the end. They are questions in the suite from the start: a request for another customer’s order, a document containing instructions aimed at the model, a question that should trigger a handover to staff. The multilingual assistant we run for hospitality guests has a fixed set of situations where the right answer is to escalate to a human, and every release is checked against them before it goes anywhere near a guest.
Watch it in production
The suite tells you how the system performs on questions you already know. Production tells you which questions you did not. We log every interaction with its retrieved sources and its score from the automatic checks, review the low-confidence ones weekly, and add the interesting cases to the suite. Cost and latency go on the same dashboard as quality, because a change that improves answers and triples the bill is a decision, not an improvement.
The point
The model is a commodity and the framework is a detail. What a company owns after a generative AI project is a set of real questions, a way of scoring answers to them, and a habit of running that score before every change. That is the product. Everything else can be swapped.